

What Is Pearl Blockchain? How It Uses GPU Mining to Price AI Compute?
What Is Pearl Blockchain
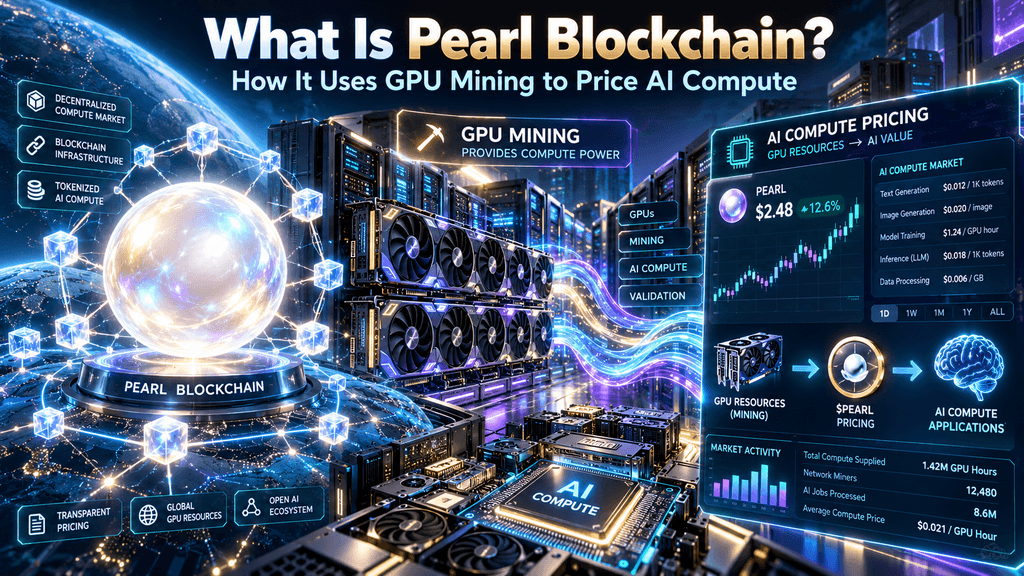
Pearl Blockchain is a Layer-1 network developed by Pearl Research Labs that replaces conventional cryptographic hashing with large-scale matrix multiplication as its consensus mechanism. Matrix multiplication forms the foundational arithmetic of neural network training and inference, allowing the same GPU operations that generate AI outputs to simultaneously produce verifiable proofs of work. The protocol, grounded in a 2025 cryptography paper by Ilan Komargodski and Omri Weinstein, extracts mining certificates from these calculations with only marginal overhead, typically measured at a few percent on production models such as Llama 70B and DeepSeek variants. The design deliberately aligns blockchain security with the dominant computational demand of the AI industry.
Operators running Pearl-certified models through the official vLLM miner or compatible community software can serve inference requests while competing for the full block subsidy and transaction fees. Zero-knowledge certificates compress the proofs so that the network can verify correctness without exposing model weights or user data. Partnerships such as the Together AI discounted inference endpoint demonstrate how PRL emissions can subsidize lower prices for end users, effectively turning token issuance into a mechanism for pricing AI compute. This dual-purpose structure positions Pearl as a live experiment in converting energy spent on intelligence production into both usable results and a scarce digital asset, creating a direct metering link between GPU cycles and monetary issuance.
Pearl Blockchain Turns AI Workloads Into Productive Mining Operations
Pearl Blockchain launched its mainnet on April 27, 2026, as a Layer-1 network that replaces conventional hash-based proof-of-work with matrix multiplication, the core arithmetic powering neural network training and inference. Developed by Pearl Research Labs, the protocol extracts mining proofs from the same GPU operations that serve large language models, allowing operators to secure the chain while producing usable AI outputs. This design, rooted in a 2025 cryptography paper by Ilan Komargodski and Omri Weinstein, aims to convert energy spent on AI workloads into both computational results and newly issued PRL tokens.
By October 2026, roughly 16.3 percent of the 2.1 billion PRL maximum supply had entered circulation, with network hashrate estimates ranging from 50 to 70 EH/s. The approach directly addresses the rising demand for GPU capacity in artificial intelligence by tying blockchain security to productive computation rather than pure cryptographic puzzles. Pearl Blockchain prices AI compute by making GPU matrix multiplications the dual engine of network security and inference delivery, enabling operators to earn PRL rewards alongside service revenue while subsidizing discounted access for end users through emissions.
How Pearl’s Proof-of-Useful-Work Extracts Mining Value From Matrix Multiplication
Pearl’s consensus mechanism, known as Proof-of-Useful-Work or cuPOW, requires miners to perform large-scale matrix multiplications on NVIDIA GPUs. These operations form the foundation of every forward pass in modern neural networks. Operators commit to input matrices, add cryptographic noise derived from recent block data and BLAKE3 hashing, then compute the product. The resulting tiles are hashed; any tile falling below the network target yields a valid block. Zero-knowledge certificates built with Plonky2 compress the proof to under 65 kilobytes, allowing on-chain verification without revealing model weights or user data. Official documentation from Pearl Research Labs confirms that the same matrix multiplications used for AI inference can simultaneously generate these proofs. Benchmarks published by the project show an overhead of 5.08 percent on Llama 70B running across four H200 GPUs and 3.9 percent on DeepSeek V3.2 across eight H200 GPUs.
This near-zero incremental cost underpins the 2-for-1 claim: one GPU cycle delivers both an AI result and a chance at the full block reward plus transaction fees. Difficulty adjusts after every block using a weighted moving average with a one-week half-life, targeting an average interval of 194 seconds. Early blocks arrived far faster because initial difficulty sat near the minimum, allowing the first 40,000 blocks to mint approximately 121.7 million PRL within 5.9 days. By early October 2026, the block reward had declined to roughly 2,262–2,277 PRL. Community and official miners support a range of NVIDIA architectures from Ampere consumer cards through Hopper and Blackwell datacenter GPUs. The protocol’s design intentionally resists ASICs, since specialized silicon optimized solely for Pearl would forfeit the ability to perform general AI work that generates secondary revenue.
Together AI Partnership Creates Discounted Inference Endpoints Subsidized by Emissions
In May 2026, Together AI launched an exclusive inference endpoint for a Pearl-certified Gemma model priced more than 25 percent below standard market rates. The discount is offset by PRL emissions generated during the same GPU workload that serves customer requests. Pearl Research Labs measured the mining overhead on production models and reported that the additional cost remains low enough for the subsidy to remain economically viable. Operators running the official vLLM miner with Pearl-certified models from Hugging Face can therefore earn blockchain rewards while supplying paid inference capacity. This structure effectively prices AI compute by allowing the network’s token issuance to lower the effective cost paid by end users.
Reporting in late September 2026 confirmed the partnership remains the primary commercial validation of the dual-purpose model. Market data from October 2026 show PRL trading near $1.40–$1.46, producing a circulating market capitalization above $470 million on roughly 342 million tokens. Daily issuance of approximately 1.086 million PRL equates to about $1.52 million at prevailing prices. The partnership demonstrates a concrete mechanism for translating mining activity into lower inference pricing, though independent analysis continues to examine how much of the network’s matrix multiplications currently serve paying customers versus pure mining workloads.
Network Hashrate Growth and GPU Market Impact Since Mainnet Launch
Network hashrate expanded from roughly 19 EH/s in May 2026 to estimates of 50–70 EH/s by early October. One June 2026 preprint calculated an earlier capacity of 24 EH/s, equivalent to about 320,000 RTX 3090-class GPUs drawing approximately 112 megawatts. The subsequent rise corresponds to more than 170,000 RTX 4090 equivalents according to community trackers. Rental markets responded quickly: budget GPU utilization on vast.ai climbed from 57 percent to 94 percent after mining software became public, and prices rose about 38 percent. Tom’s Hardware reported that the rush temporarily displaced some research workloads as operators redirected cards toward Pearl.
Profitability has compressed as difficulty increased. An RTX 4090 that once generated higher daily revenue now yields roughly $7–$8 net at $0.10 per kilowatt-hour electricity costs, while an RTX 5090 produces around $10. Official vLLM mining remains limited to H100 and H200 cards, but community miners such as SRBMiner and BzMiner support broader consumer hardware. Pools charge fees between 0 and 2 percent and distribute rewards hourly under PPLNS. The quick hashrate growth illustrates how the promise of dual revenue streams can quickly attract capacity, yet it also raises the bar for sustained profitability as emission rates decline and more operators join.
Tokenomics of PRL: Fixed Cap, Declining Rewards, and Early Distribution Dynamics
PRL carries a hard maximum supply of 2.1 billion tokens with no premine, no investor allocation, and no developer treasury. Issuance follows a smooth polynomial decay formula rather than discrete halvings. The reward begins at 3,229.64 PRL in the genesis block and declines by a small amount with every subsequent block. By block height of approximately 124,000 in early October 2026, the reward stood near 2,277 PRL. Cumulative supply reached about 336–342 million tokens, or 16 percent of the cap. Half the maximum supply is projected to enter circulation near the end of 2029 at the target block interval.
Early low difficulty concentrated a substantial portion of the initial supply: the first 40,000 blocks alone accounted for roughly 37 percent of all PRL mined by October. Coins become spendable after 100 confirmation blocks, roughly five and a half hours. The base layer retains Bitcoin’s UTXO model and longest-chain rule, forked from the btcd codebase. Addresses begin with the prl1 prefix and use Taproot exclusively. Transaction fees accrue to the miner who finds the block. This transparent emission schedule ties the monetary base directly to verified GPU computation, creating a measurable link between AI capacity growth and token supply expansion.
Official vLLM Miner Versus Community Mining Software
Pearl Research Labs provides an official miner built as a plugin for the open-source vLLM inference engine. The plugin replaces the model’s matrix-multiplication routine with NoisyGEMM, allowing the same forward pass to generate both inference output and mining proofs. Pearl-certified models are published on Hugging Face. Official documentation states that the approach requires H100 or H200 GPUs and a running pearld node plus pearl-gateway. Solo mining produces lumpy rewards: operators receive the full block subsidy and fees only when they find a valid block.
Community miners such as SRBMiner-MULTI, BzMiner, WildRig Multi, and PeakMiner support a wider range of NVIDIA cards from RTX 20-series through Blackwell, with some AMD compatibility in certain releases. These tools typically operate against mining pools and include optional model-serving modes. Dev fees range from 0 to 2 percent. The official path prioritizes genuine dual-purpose operation, while community software emphasizes pure hashrate efficiency. Operators choose based on hardware availability and whether they can secure paying AI workloads to offset electricity costs.
Empirical Studies Question the Volume of Paying AI Workloads
A June 2026 preprint titled “The Usefulness Gap in Proof-of-Useful-Work” examined 8,012 workers and concluded that the dominant mining software contained no inference code. The study reported that the protocol verifies correct matrix multiplication but does not confirm that the matrices originated from customer-requested AI jobs. Researchers generated valid shares on NVIDIA, AMD, CPU, and Apple Silicon hardware using random matrices. At the then-prevailing price of $0.76, ROI ranged from strongly negative on expensive datacenter cards to modestly positive on budget consumer GPUs.
The paper estimated the network produced zero useful AI computation relative to paid demand at the time of measurement. Pearl Research Labs and subsequent commercial partners maintain that the cryptographic design allows real inference to generate valid proofs with negligible overhead. The Together AI endpoint provides one production example of paid workloads subsidized by emissions. The tension between verified matrix multiplications and verified paid inference remains an active area of scrutiny for both researchers and operators evaluating long-term economics.
Hardware Requirements and Profitability Calculations for Current Miners
Supported hardware encompasses a wide range of architectures, including NVIDIA's Ampere, Ada Lovelace, Hopper, and the emerging Blackwell designs. The official mining documentation places significant emphasis on the H100 and H200 graphics cards, which are particularly suited for the vLLM path. Community benchmarks have reported that an RTX 4090 can deliver an impressive performance of approximately 304 TH/s while consuming around 326 watts under optimized settings. Furthermore, the upcoming RTX 5090 is anticipated to exceed 400 TH/s, showcasing the advancements in GPU technology. Power consumption and rental rates play a crucial role in determining net returns for operators. As of October 2026, with prices hovering around $1.40 and network conditions yielding approximately 0.02 PRL per TH/s per day, consumer-grade graphics cards can generate a modest positive cash flow after accounting for electricity costs, provided that power expenses remain close to $0.10 per kilowatt-hour.
In contrast, datacenter rentals tend to hover around break-even points or even yield negative returns unless operators are also able to capture revenue from inference tasks. Mining pools, such as PearlNet, offer competitive rates with fees set at 2 percent and hourly payouts beginning at 1 PRL. Operators must carefully consider the continuous decline in rewards, the rising difficulty of mining, and the potential fluctuations in GPU rental markets. The dual-revenue model can enhance the overall economics of mining operations, but it only becomes truly beneficial when a significant portion of matrix multiplications is directed towards paying customers rather than being solely focused on pure mining activities.
Protocol Upgrades Expand Model Support and Numerical Precision
Since the launch of the mainnet, the network has undergone a series of significant consensus upgrades aimed at enhancing its functionality and performance. Notably, a hard fork that took place in June 2026 introduced support for advanced mixture-of-experts models, which are designed to optimize the processing capabilities of the network. Following this, several soft forks were implemented to refine the noise requirements and update the versions of certificates used within the system. In September 2026, Pearl made a groundbreaking announcement regarding the publication of an FP8 floating-point mining scheme. This innovative scheme utilizes quantization techniques to ensure that security is maintained while effectively doubling the throughput on hardware that is compatible with these advancements.
Discussions surrounding FP4 designs are still ongoing, indicating that there is a continued interest in exploring new possibilities. These recent changes are important, as they ensure that the mining function remains in alignment with the numerical formats that are preferred by production AI systems, which are increasingly becoming the standard in the industry. Furthermore, the verification techniques being employed are based on cutting-edge research that successfully reproduces GPU arithmetic with precision on CPUs. This ensures that the proofs generated by the network remain sound and reliable across different generations of hardware, thereby enhancing the overall integrity and trustworthiness of the system.
Market Performance Reflects Both Narrative Strength and Supply Pressure
PRL experienced a remarkable surge, reaching an unprecedented all-time high that exceeded $1.70 in late September 2026. Following this peak, the price underwent a consolidation phase, stabilizing within the range of approximately $1.40 to $1.46 by mid-October. During this period, the circulating market capitalization of PRL surpassed an impressive $470 million, while the fully diluted valuation approached a staggering $2.9 billion. It is noteworthy that the daily trading volume across the available trading venues remains relatively modest when compared to the overall market capitalization.
The early concentration of supply, stemming from the low-difficulty launch period, continues to exert a significant influence on the distribution of circulating coins. The notable absence of a premine or venture allocation is often shown as a key distinguishing feature of PRL. However, it is essential to recognize that the rapid issuance of coins during the initial phase still resulted in a concentration of holdings among the earliest participants in the market.
Practical Paths for Operators Seeking Dual Revenue Streams
Operators have the opportunity to acquire cloud GPU packages through various platforms that specialize in managing mining software and facilitating payout collection. This innovative approach effectively eliminates the necessity for personal hardware, allowing operators to engage in mining activities without the burden of maintaining physical equipment. For those who prefer self-hosted setups, it is essential to have a synchronized pearld node, a designated wallet address, and either the official vLLM stack or a community miner that is configured to connect to a mining pool. It is important to note that Pearl-certified models guarantee the presence of the necessary mining instrumentation during the forward pass, ensuring optimal performance.
To assist operators in their endeavors, tracking tools are available that meticulously monitor various parameters, including mining difficulty, reward size, and estimated earnings per terahash per second (TH/s). The economic viability of these operations becomes increasingly robust when revenue generated from inference or emission subsidies can effectively offset the electricity and capital costs that are typically associated with pure mining activities. This dynamic creates a more favorable financial landscape for operators, enhancing the overall attractiveness of participating in this innovative mining ecosystem.
How AI Compute Markets and Energy Use Could Evolve Over Time
By transforming the prevalent GPU operation into a monetary primitive, Pearl establishes a direct and effective metering mechanism that accurately reflects the intensity of AI computation. The energy that would typically compete exclusively with Bitcoin-style hashing can now play a significant role in contributing to both the production of intelligence and the security of the network. This innovative design remains hardware-agnostic within the expansive NVIDIA ecosystem and actively resists any form of specialization that could potentially sever the crucial link to productive and useful work.
As the demand for larger model scales and increased inference continues to grow, it will be essential to test whether this dual-purpose model can effectively scale without encountering the usefulness gap that was identified in earlier empirical research. Operators, researchers, and infrastructure providers are now viewing Pearl as a live and ongoing experiment aimed at aligning blockchain incentives with the tangible and physical realities of AI computation. This alignment is critical for ensuring that the benefits of AI and blockchain technology can be realized in a synergistic manner, paving the way for future advancements in both fields.
🔥 Beyond the Headlines: What KuCoin 5.0 Means for You
Market news moves fast — but where you act on it matters just as much. This October, KuCoin launches KuCoin 5.0, transforming KuCoin into a rebuilt platform. Here's what actually changes for you:
-
One account for everything. Older platforms split your money across separate "spot," "margin," and "futures" accounts and expected you to understand why. KuCoin 5.0's unified account removes that entirely — deposit once, and everything is simply there (only available to VIPs for now).
-
Stocks, indices, and commodities. KuCoin 5.0 expands beyond crypto into global markets. When crypto chops sideways and equities rally (or the reverse), you rotate in minutes instead of opening a brokerage account and waiting days for fiat rails.
-
Real-world assets (RWA). Tokenized exposure to traditional assets like commodities, right inside your crypto account. One of the fastest-growing segments in global finance is no longer reserved for institutions — you access it from the same balance you trade with.
-
Earn while you learn. Not ready to trade? KCUSD lets your stablecoins earn daily, auto-compounding interest. The lowest-stress way to put your idle deposit to work for 4% yield.
-
An AI assistant in plain language. Ask questions, get market context, understand what you're looking at — built into the platform, no jargon required.
-
An app that doesn't overwhelm. Faster, cleaner, and consistent — intuitive from the first tap, not after a tutorial.
-
Safety you can check, not just trust. A MiCAR-licensed EU entity, Proof of Reserves you can verify yourself, and internationally certified security (SOC 2 Type II, ISO 27001:2022).
Create your account in minutes — and start on the platform built for where crypto is going, not where it's been.
FAQs
What hardware is required to participate in Pearl mining effectively?
NVIDIA GPUs from Ampere onward are supported, with official software optimized for H100 and H200 datacenter cards and community miners extending compatibility to consumer RTX series. Operators need sufficient VRAM for the chosen model, recent drivers, and either a full node or pool connection. Power efficiency and rental rates determine net profitability more than raw hashrate alone.
How does the Together AI partnership affect inference pricing?
The endpoint offers selected models at more than 25 percent below standard rates, with the discount funded by PRL emissions generated during the same GPU workload. This creates a concrete example of mining activity lowering the cost of AI services for end users while operators earn both token rewards and service revenue.
Is all mining activity currently producing paid AI outputs?
Independent research in mid-2026 found that dominant software accepted random matrix multiplications without requiring customer-requested inference. The protocol verifies correctness of the arithmetic but does not enforce origin from paid workloads. Production partnerships provide counter-examples, yet the share of paid versus pure-mining computation continues to evolve.
What is the current emission rate and its effect on supply?
Daily issuance stands near 1.086 million PRL, equivalent to roughly $1.5 million at mid-October 2026 prices. The declining reward curve means the rate will continue to fall, with half the maximum supply expected near the end of 2029 under target block times.
Can operators earn revenue from both mining and inference simultaneously?
Yes, when running Pearl-certified models through the official vLLM miner or compatible community software that serves real requests. The overhead remains low enough that the same matrix multiplications can generate both block proofs and customer outputs, provided paying demand exists for the models being served.
How does difficulty adjustment work on the network?
Difficulty retargets after every block using a weighted exponential moving average with a one-week half-life. The mechanism aims for 194-second average intervals and has successfully stabilized block times after the initial low-difficulty period.
Disclaimer: This content is for informational purposes only and does not constitute investment advice. Cryptocurrency investments carry risk. Please do your own research (DYOR).